
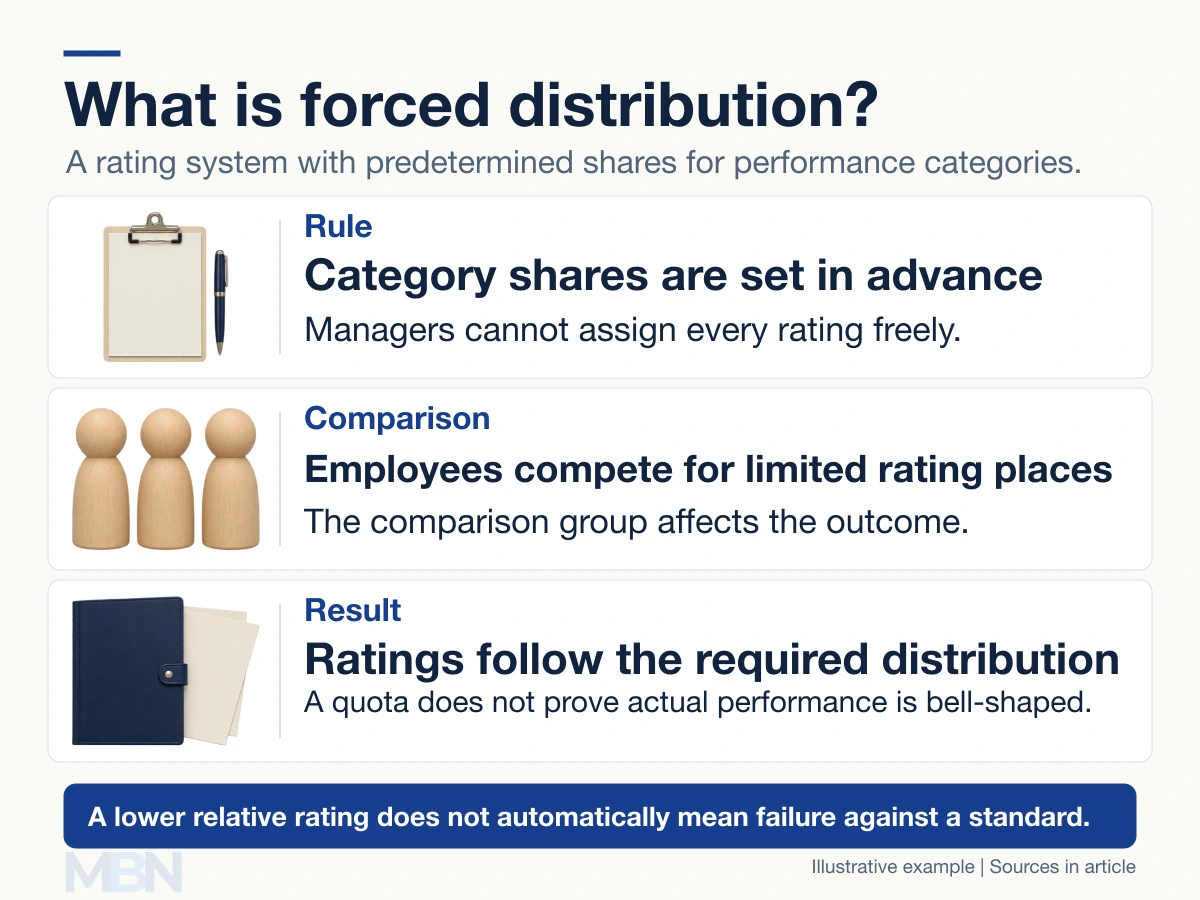
Forced distribution is a performance-appraisal method that requires employee ratings to fit predetermined category shares. Managers must place specified proportions of a comparison group into different rating levels.
The defining feature is the distribution rule, rather than the number or names of the categories. Three levels are possible, but there is no universal three-category system.
How does the method work?
A company might specify how many employees can receive a higher rating and how many must receive middle or lower ratings. Managers assess employees, but the final allocation must also satisfy the required split.
This differs from rating everyone against an absolute performance standard without a category quota. Under standards-based assessment, every employee could theoretically meet the same standard. Under a fixed distribution, everyone cannot receive the highest category.
Forced ranking usually means ordering people relative to one another. Forced distribution assigns people to categories according to required shares. The practices can overlap, but ranking alone does not necessarily impose category quotas.
An example with 20 employees
Suppose a fictional organization requires a 20/70/10 split across higher, middle and lower ratings for a group of 20 employees. There would be four places in the higher category, 14 in the middle and two in the lower category.
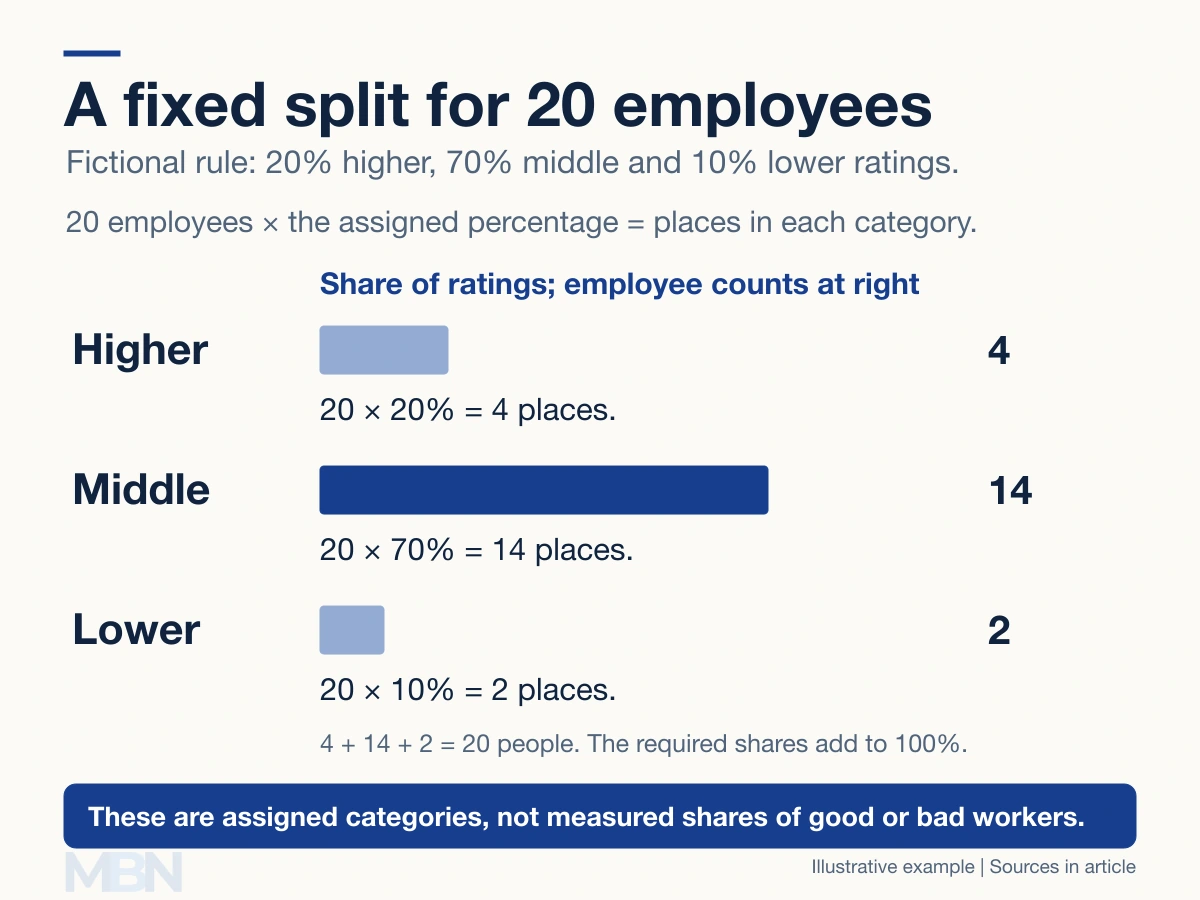
Those numbers follow from the rule. They do not independently establish that exactly two employees are failing their jobs. Even a strong team would still need two lower relative ratings under this hypothetical arrangement.
The comparison group matters. Someone’s position within a particularly strong group can differ from their position in a weaker one, even if their own work is unchanged. A category quota also does not demonstrate that underlying performance follows a normal, or bell-shaped, statistical distribution.
Why do organizations consider it?
Supporters seek clearer differentiation and less rating inflation, in which too many employees receive very high ratings. They also argue that differentiated ratings can strengthen incentives. These are proposed mechanisms, rather than guaranteed results.
A real-effort experiment by Johannes Berger, Christine Harbring and Dirk Sliwka found higher productivity under forced distribution in some conditions. The effects were less clear after participants had experience with an unrestricted system, and the method became harmful when workers could sabotage one another.
What can happen to collaboration?
Linda Loberg, Stephan Nüesch and Johann Nils Foege examined forced distribution in three experiments published in 2021. Participants completed a card-sequencing task faster when working alone under the system, but more slowly when working in teams. Knowledge sharing also fell in their team experiment.
These findings concern specific experimental tasks and incentives. They do not show that every company would experience the same result. They help explain why a system that encourages individual competition can work differently when colleagues depend on each other.
Does a lower rating mean dismissal?
Dismissal, pay, promotion and development are separate policy decisions. A forced distribution can influence them, but firing a fixed percentage is not part of every definition or implementation.
It is also possible to set a ceiling on top ratings without requiring a fixed percentage of failing ratings. The precise rule matters more than labels such as stack ranking or bell-curve rating.
Last checked and updated on November 3, 2026 by the MBN editorial team.